

We use LLMs for a surprising number of problems that aren't generation problems. As agents get access to more tools, more of their work is going to be about deciding what to do rather than generating what to say.
These are decision problems. And in many cases, the possible outcomes are already known.
That distinction became interesting to me when I started experimenting with Jev from TypeSafe.
We've been working on tool search in Agentkit.
The basic problem is straightforward. An agent might have hundreds of tools available, but a user request usually maps to a small number of them. We need to retrieve the relevant candidates and determine which one best matches the user's intent.
Our existing search layer handles the first part well. The harder part is semantic relevance.
Take: "Email my manager about the outage."
A lexical search can surface tools for searching or reading email because those descriptions have strong word overlap with the request. But the intended action is to send an email.
I tried using Jev as a second-stage reranker over the results from our existing search.
The result was a useful improvement: a tool that ranked fifth in the initial results moved to the top once the candidates were evaluated semantically. The complete path stayed around 200ms in our testing.
What I found more interesting than the ranking improvement was the underlying architecture.
We didn't need another generative model to solve the problem.
The search system already gave us a bounded set of possible actions. What we needed was a model that could make a decision between them.
That is a different primitive from text generation or workflow authoring.
The other thing I wanted to test was what happens when the input isn't specific enough to make a decision.
For example: "We are doing agents and MCP stuff."
There are multiple reasonable destinations for that request. Jev didn't confidently select one; it split its probability across the possible choices. That's useful information for the application.
Instead of treating every model response as an instruction to proceed, the application can use the confidence of the decision as part of its control flow. High confidence can continue the workflow. Low confidence can trigger another question.
This is an important difference between a model that generates an answer and one that helps an application decide what to do next.
Here is the flow an agent follows with the Search Tools API today (see the product update). The Jev reranking above was an experiment and is not part of the API yet; in that setup it sat between steps 2 and 3.
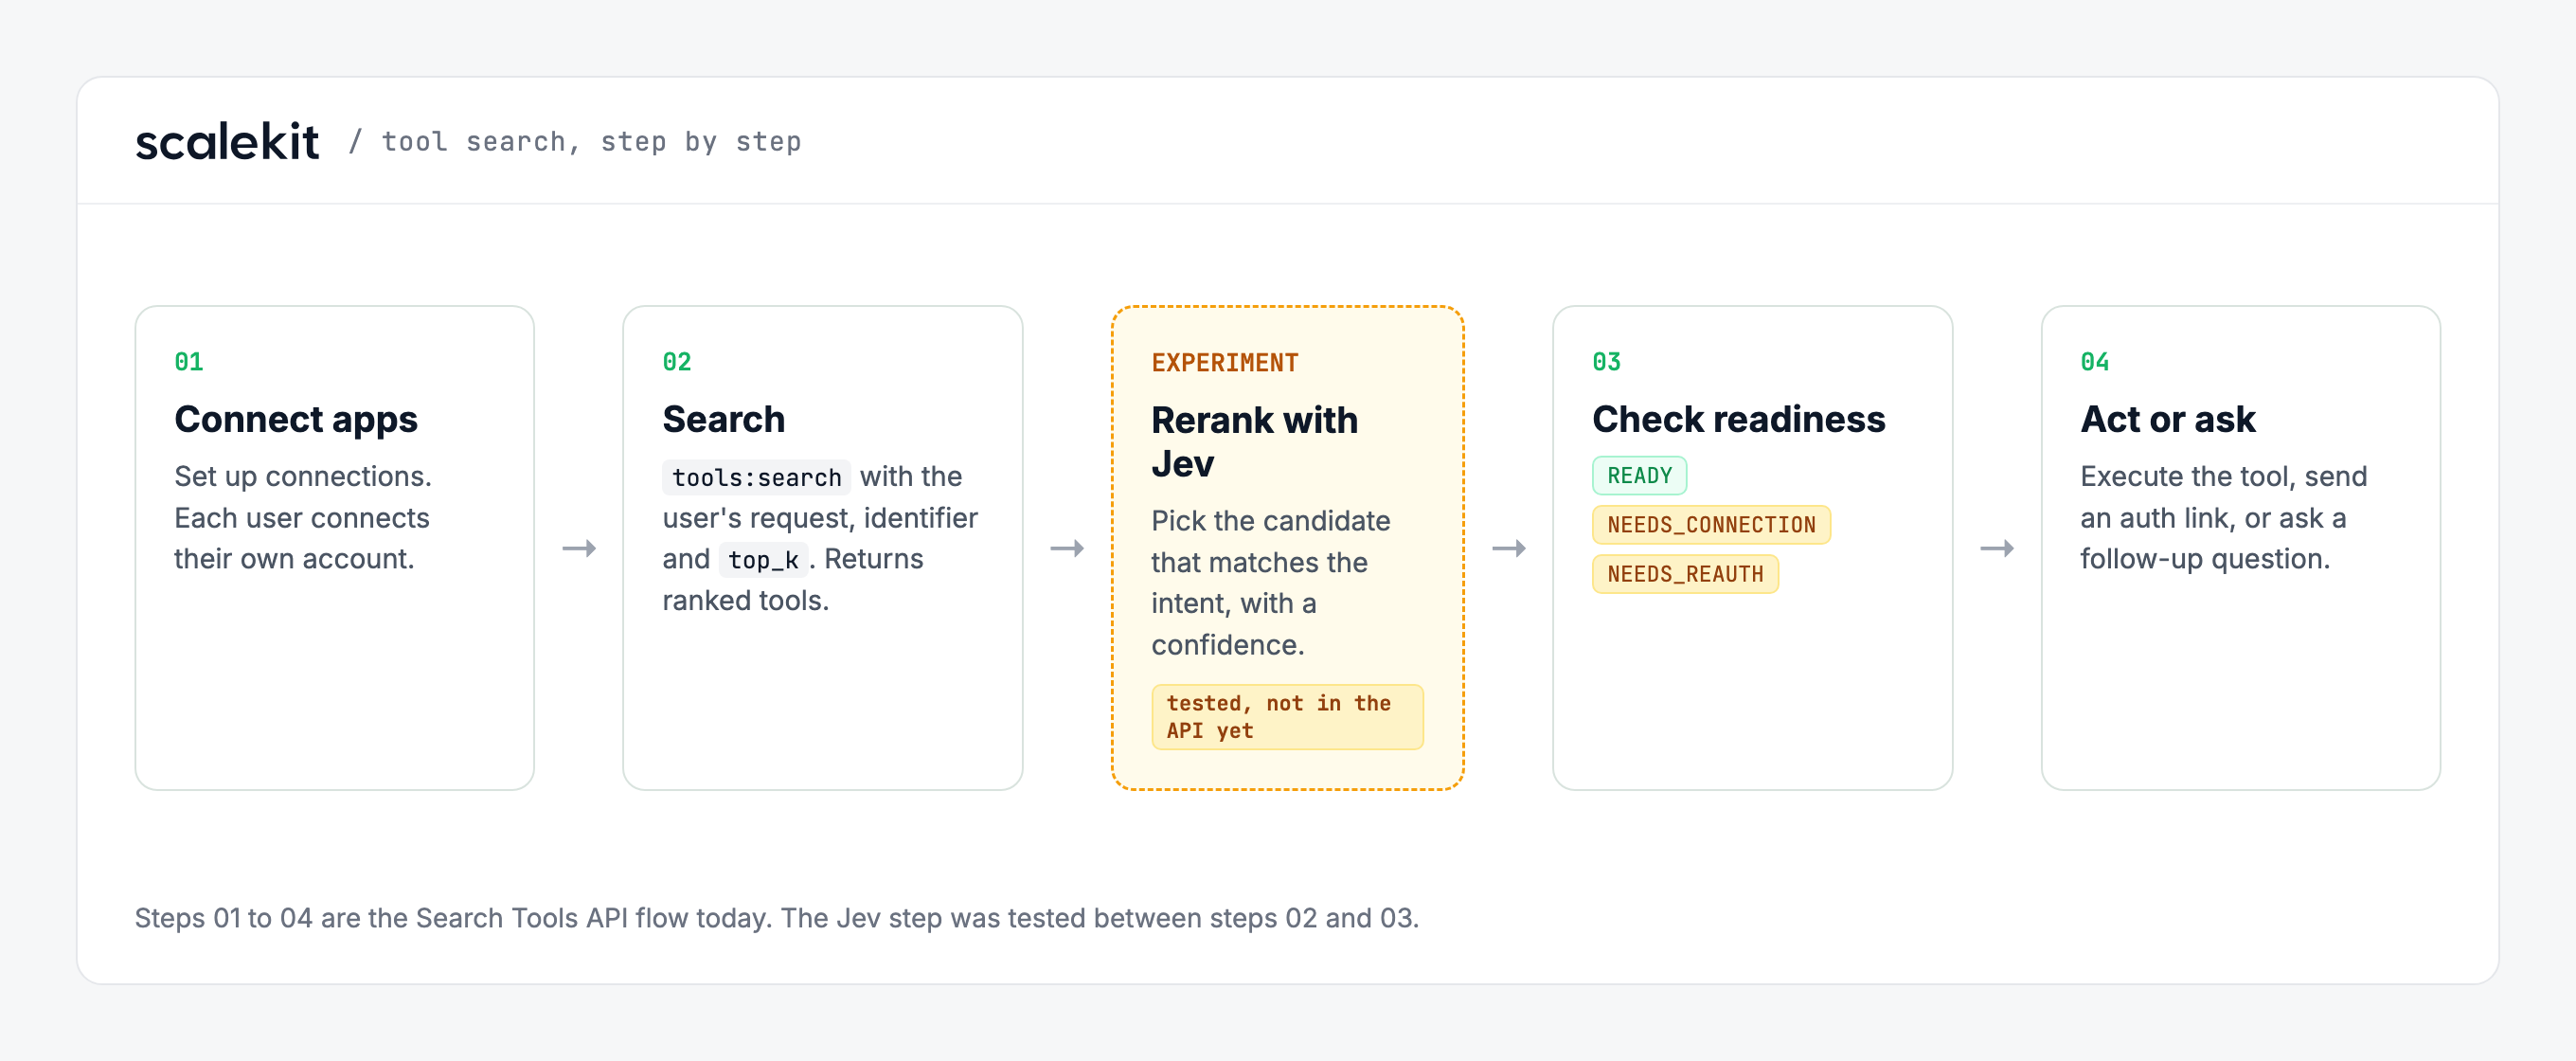
Here is what steps 2 and 3 look like for the request "send an email". The agent sends the request with the user's identifier:
curl -sS -X POST \
  "$SCALEKIT_ENVIRONMENT_URL/api/v1/tools:search" \
  -H "Authorization: Bearer $TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
    "query": "send an email",
    "identifier": "user_123",
    "top_k": 5
  }'
The response ranks gmail_send_message first, with the user's Gmail account ready to use, and returns slack_send_message with an empty connections list, because this user has not connected Slack:
{
  "tools": [
    {
      "name": "gmail_send_message",
      "provider": "GMAIL",
      "score": 0.87,
      "connections": [
        {
          "connection_name": "gmail",
          "connected_account_id": "ca_24834495392086178",
          "readiness_state": "TOOL_READINESS_STATE_READY"
        }
      ]
    },
    {
      "name": "slack_send_message",
      "provider": "SLACK",
      "score": 0.61,
      "connections": []
    }
  ]
}
The agent can call the Gmail tool with that connected account ID, and offer the user a link to connect Slack. In the Python SDK, the same search is one call:
results, _ = scalekit_client.tools.search_tools(
    query="send an email",
    identifier="user_123",
    top_k=5,
)
Search reranking is just one example of where a model like Jev can be useful.
There are many parts of our products where the system needs to choose between a known set of possibilities. Customer onboarding is one example: a user describes what they are trying to build, and the system needs to determine which capability or workflow is relevant. Workflow automation and state selection have similar properties. There are also opportunities around model routing and tool routing, where the system needs to make a decision rather than generate a response.
That is where I think Jev gets interesting as a product primitive. It can sit alongside the systems we already have rather than replacing the generative model.
Diogo Almeida has written about using Jev for things like semantic model routing and tool routing. We tested the same idea for search: our in-house search engine narrows the tool catalog to a set of candidates, and Jev provides a semantic reranking layer to determine which tools are most relevant to the agentic action.
The broader pattern is simple: retrieval, ranking, and generation are different problems. They don't necessarily need to be handled by the same model.
As we continue adding more tools and capabilities to agents, I expect we'll find more places where a specialized model can handle one part of the problem better than asking a generative model to do everything. The more we explore Jev, the more use cases we find for it, from search reranking to customer onboarding, workflow automation, state selection, model routing, and tool routing.
We're excited to introduce Jev into more parts of Scalekit and see how far this can go. Experience it here: https://auth.scalekit.com/a/auth/signup and let us know what you think. There are many more places where a specialized decision model can make our products feel a little more like magic.
Interested in how tool calling auth works at scale? Read our deep-dive on credential ownership across agent tool-calling patterns and how LangChain tool calling works in production systems.